Question/Issue:
When trying to deploy our customized quantized int8 model (onnx format) using the Edge Impulse, the page would report a series of errors. However, when we deploy the pruned fp32 model (onnx format), it works fine.
Project ID:
1132429
Context/Use case:
[Provide context or use case where the issue is encountered]
Summary:
[Provide a concise summary of the bug]
Steps to Reproduce:
- Upload the int8.onnx file through the “Upload your model” tab
- After uploading, let Edge Impulse start processing job
Expected Results:
Successful compiling as fp32 model
Actual Results:
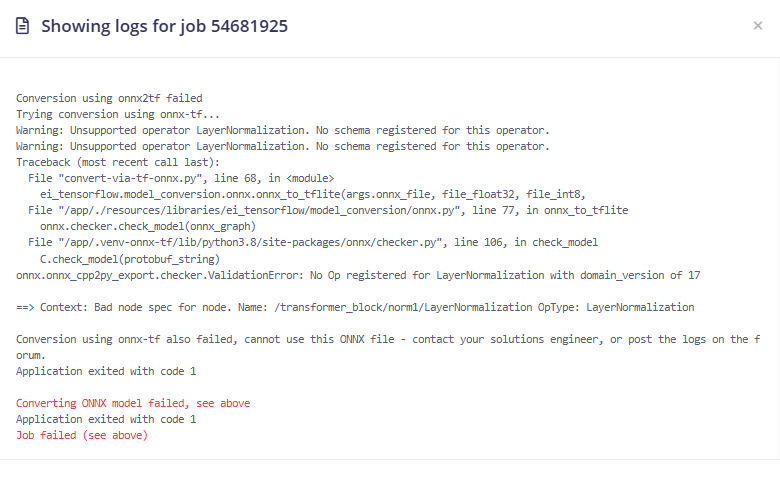
A series of error report
Reproducibility:
- [ ] Always
Environment:
- **Edge Impulse Online Platform
Logs/Attachments: